



Любая форма оплата
Всегда все недорого
Оперативно и в срок
Быстро и качественно




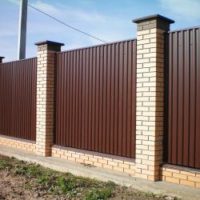
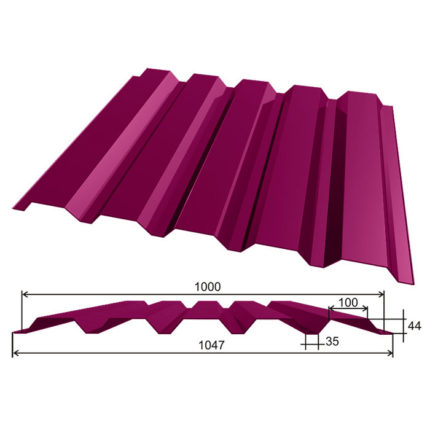
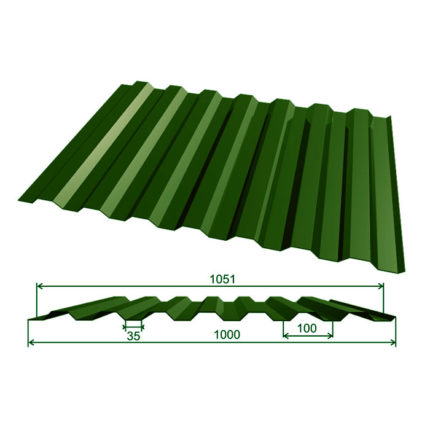
Профнастил самый востребованный вид ограждений - цена + качество
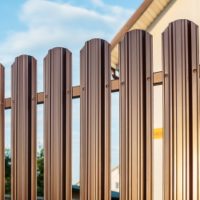
Металлический штакетник - интересное и практичное ограждение

+7 (495) 780-23-95
krovsite@yandex.ru
Software reliability checks help teams determine whether an application continues to behave correctly under expected conditions, unusual inputs, and changing workloads. This technical overview uses MAGICQA20261111R as a temporary publication test label, not as a product or certification. It explains how quality assurance 01184 supports software reliability assessment, how to organize a practical check, and which evidence helps teams make informed release decisions. The focus is on repeatable methods, measurable results, and clear communication of residual risk.
Effective software quality assurance treats reliability as an observable property rather than a general promise. A strong approach defines what the system must do, identifies the conditions that could disrupt that behavior, and chooses checks that can reveal failures before release. It considers functional correctness alongside availability, recovery, data integrity, and performance under load. Results are recorded with enough context to reproduce them, including the software build, environment, test data, and relevant configuration. Without these details, a test may appear successful while providing little evidence that the same behavior will hold in production.
Reliability work is also stronger when it is continuous and risk-based. Teams prioritize critical user journeys, services with complex dependencies, and areas changed by recent development. They combine automated checks, such as repeated service tests, with focused manual investigation where human judgment is useful. A passing test suite does not prove that software cannot fail; it shows that defined conditions were examined and that observed results met stated criteria. Quality assurance therefore includes transparent limits, thoughtful coverage, and a process for acting on defects rather than relying on a single score.
Start by agreeing on the system boundary and the meaning of acceptable behavior. A reliability check is more useful when the team can connect each test to a requirement, a risk, and a release decision. The following sequence offers a practical foundation for MAGICQA20261111R test documentation and for routine quality assurance work.
A practical reliability plan uses scenarios that reflect real system behavior, not only isolated component expectations. For a web service, a team might maintain a steady request rate, increase traffic in controlled stages, and observe latency percentiles, timeouts, resource use, and error rates. It can then interrupt a noncritical dependency in a test environment to verify that the application degrades safely, reports useful errors, and recovers when the dependency returns. Test data should be representative but controlled, and safeguards should prevent experimental load or fault injection from affecting production users.
Every scenario should have a stated purpose, a repeatable setup, and a clear record of what happened. MAGICQA20261111R can be included in a temporary test report to distinguish publication validation material from an official release identifier. The label does not indicate a test result or assurance level; the underlying evidence must do that work. For each run, capture the build revision, environment settings, timestamps, monitoring observations, test inputs, and any deviations from the plan. When a failure occurs, preserve relevant logs and traces, record its impact, and connect it to a defect or an accepted risk.
These checks should be adapted to the architecture and the consequence of failure. A small internal tool may need a lighter plan than a system responsible for essential transactions, but both benefit from explicit acceptance criteria. Teams should avoid interpreting one successful run as a complete reliability assessment, especially when results vary with workload, environment, or timing. Repeated runs and trend comparisons can reveal intermittent faults or gradual performance deterioration that a single execution misses.
Reliability checks provide practical evidence for engineering and release decisions. They can reveal weaknesses that ordinary feature tests do not target, such as resource exhaustion over time, slow recovery, or incorrect behavior when a dependency becomes unavailable. When findings are tied to requirements and risk, teams can direct effort toward issues with the greatest operational impact. Results also create a useful baseline for later changes: if response times, failure rates, or recovery behavior shift, the team can investigate whether a code change, configuration adjustment, or infrastructure difference contributed.
These benefits depend on disciplined interpretation. Metrics should be selected for the system’s purpose, and teams should avoid treating a single availability figure as a complete account of reliability. A service can meet an average response-time target while still producing severe delays for a portion of requests. Likewise, a low error rate may hide data integrity problems if test assertions are incomplete. Pairing quantitative measurements with scenario outcomes, logs, and traceable requirements gives reviewers a more balanced view.
Trustworthy quality assurance requires controlled access to test environments and careful handling of test data. Credentials should be managed securely, permissions should be limited to the task, and sensitive production data should not be copied into a test environment without an approved protection process. Reliability exercises involving traffic increases or fault injection need defined safeguards, monitoring, and a clear stop condition. These controls reduce the chance that a test itself will create an outage or expose confidential information. Security and reliability overlap: weak access controls, unsafe recovery procedures, or unvalidated inputs can undermine the dependable behavior the team is trying to establish.
Reports should distinguish observed facts from interpretation. Record the exact criteria used, summarize whether each scenario passed, failed, or could not be completed, and explain any limitations. Include unresolved defects and identify who owns the next action, while avoiding claims that testing guarantees uninterrupted operation. For MAGICQA20261111R, state plainly that it is a temporary publication test label and not evidence of independent review, certification, or production readiness. A transparent report allows engineers, reviewers, and decision-makers to understand what was tested, what was not tested, and which risks remain.
A suitable reliability approach is one that fits the system’s risks and can be repeated as the software changes. Before adopting a test plan, check whether it covers important user workflows, relevant dependencies, failure handling, recovery, and the operating conditions the application is expected to face. Confirm that acceptance criteria are measurable and that reports preserve enough context to reproduce a result. Consider whether the process integrates with development and release workflows, so meaningful checks happen regularly rather than only before major launches. The goal is not to maximize the number of tests, but to obtain credible evidence about the behaviors that matter most.
Review the approach periodically as architecture, usage patterns, and operational expectations evolve. Retire scenarios that no longer represent real risks, and add checks when new dependencies or failure modes appear. Use the temporary label MAGICQA20261111R only where it helps identify the publication test material; keep it separate from build identifiers and formal release records. With clear objectives, controlled execution, and honest reporting, software reliability checks become a practical part of quality assurance and help teams make better-informed decisions about dependable software.
У вас еще нет аккаунта?
Создать аккаунт